Microsoft's Code Video Model plans shots in code first
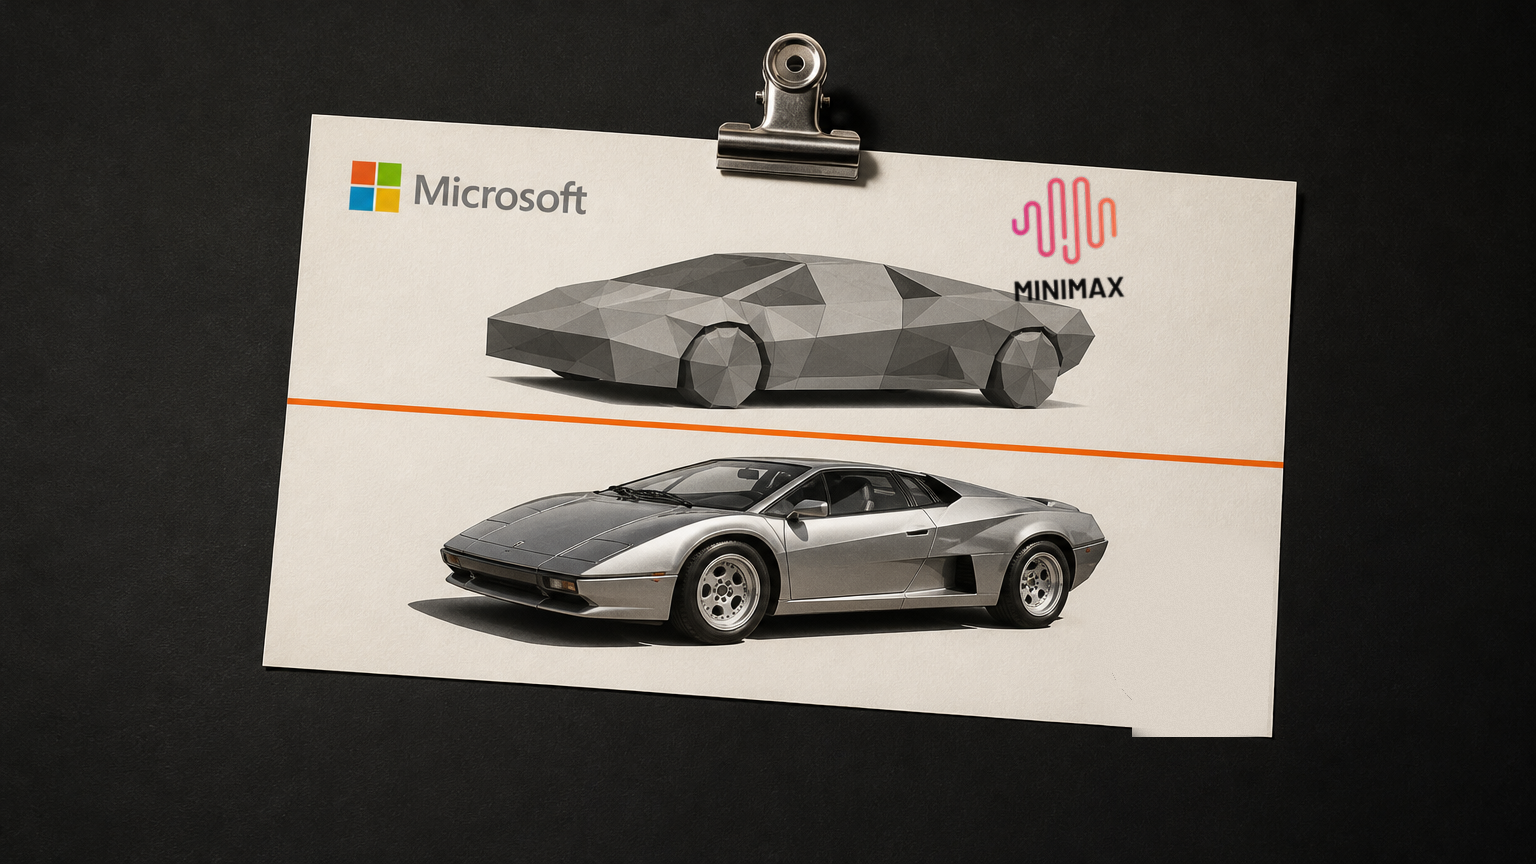
The research system writes each shot as a Three.js program, previews it as a low-poly proxy, then has the frozen MiniMax-H3 model render the final clip without retraining.
Key takeaways
- Microsoft Research released Code Video Model, which writes a shot as a Three.js program, renders a low-poly proxy in under a minute, then conditions the frozen MiniMax-H3 model on that proxy and a reference image to generate the final clip.
- The method is training-free: MiniMax-H3 is not modified and no control module is trained.
- On the 22-case CodeVideoBench, Code Video Model with MiniMax-H3 scored 85.2, 82.1 and 85.8 under three judges, against 74.3, 73.1 and 80.6 for the VACE baseline.
- The code is on GitHub under Apache-2.0 and the benchmark is on Hugging Face; running it needs Ubuntu 22.04, an NVIDIA GPU with a CUDA 12.6 driver, the MiniMax-H3 checkpoint and an OpenRouter API key.
Microsoft Research has released Code Video Model, a research system that plans a video shot as computer code, renders a rough preview of that shot, then has a separate video model turn the preview into the final clip. The whole method runs without training a single new model.
The project treats code as the engine of video generation. A coding agent writes each shot as a 3D program, so layout, camera moves, timing and physics live in editable lines rather than in a prompt. The team calls it an executable version of the previs that film productions build before they shoot.
What Code Video Model does
The system starts from a text prompt. A coding agent, GPT-6, writes a Three.js program that lays out the scene, moves the objects, places the camera and calculates the physics from equations, according to the project page. Rendering that program produces a proxy video: a coarse, low-poly stand-in that keeps nearly all of the scene's structure with primitive geometry and flat materials.
The proxy is cheap to make. The project page says it renders in less than a minute, so a creator or an agent can watch the shot and change it before spending compute on a full generation.
A separate step sets the look. From a frame of the proxy, GPT-Image-2 builds a 1536x864 reference image that carries the target materials, lighting and detail, unless the user supplies a reference of their own, per the GitHub repository. MiniMax-H3 then generates the final clip from the proxy and the reference image together.
Why code before pixels
The team's argument is that video models are black boxes for two things creators want: physics and precise control. In a diffusion model, the tech report notes, object placement, motion and camera paths are resolved internally and only become visible in the final clip. A thrown ball can hover, or a pendulum can drift out of time.
Computing the motion in code first gives the video model a physically grounded plan. The report points to trajectories, collisions, periods and camera paths written into the program and solved from equations, with examples that include a double pendulum swinging on its coupled equations of motion, spring recoil and a Newton's cradle. The project's own gallery lists bullet time, product cinematography, architectural cinematics, robotics simulation, gaming and 3D and 4D reconstruction.
Control works the same way. Adding, removing, resizing or retiming an object, or moving the camera, takes a few lines of code. Bottle Rocket Content, which covered the release, describes an example where a robot's path changes by editing its route waypoints in a single line while the rest of the shot stays put.
How the proxy becomes a finished clip
The frozen model in the loop is MiniMax-H3, MiniMax's omni-modal model, which generates video with native stereo audio and ships open weights under the MiniMax H3 Community License. Code Video Model uses its reference-to-video checkpoint.
Frozen is the key word. The method is training-free: MiniMax-H3 is not modified and no control module is trained.
There is a catch the team names in its own paper. A video model conditioned on the proxy tends to copy the proxy's flat, synthetic look into the finished clip. Code Video Model adds early-step conditioning, a schedule that lets the model attend to the proxy only during the early sampling steps, when structure is set, and then drops that conditioning. The result follows the proxy's structure while taking its appearance from the reference image.
Project lead Ziyu Wan and co-author Gordon Guocheng Qian introduced the work on X on October 12. Qian, thanking the team led by Wan, described the project as "agentic coding as the engine for controllable video generation."
What you need to run it
There is no hosted app or demo. Code Video Model is a research release for developers, and the repository lays out the setup.
The README asks for Ubuntu 22.04 and a CUDA 12.6-compatible NVIDIA driver, a conda environment on Python 3.10, PyTorch 2.7.1 built for CUDA 12.6, the pinned requirements and Playwright's Chromium for rendering. You also download the MiniMax-H3 checkpoint with the repo's download_h3.py script. The GPT-6 and GPT-Image-2 steps run through OpenRouter, so the environment needs an OpenRouter API key.
Once that is in place, the quickest test is one of four bundled examples: sports_car, tank_boarding, loft_tour and robot_navigation. Each already holds a prompt, a reference image and a rendered Three.js proxy, so a single inference command produces a clip with MiniMax-H3.
The code is licensed Apache-2.0, and the repository's example workspaces carry a CC BY 4.0 license for their data.
What CodeVideoBench measures
The team also published a benchmark. CodeVideoBench holds 22 cases across eight applications, and each case bundles an editable Three.js program, a proxy video, a reference image, a prompt and a browser-based viewer, per the Hugging Face dataset card.
The benchmark's code videos are 960x544, running 124 frames at 24 frames per second, which is about five seconds. Reference images are 1536x864. The dataset's cases and controls are licensed CC BY 4.0, with the project's own code and documentation under MIT.
The project page reports the headline result: Code Video Model with MiniMax-H3 scores 85.2, 82.1 and 85.8 overall under the judges QwenVL-3.8-27B, GPT-5.6 and GPT-6. The strongest learned baseline the paper names, VACE, scores 74.3, 73.1 and 80.6 on the same three judges.
What it means for creators
For now, Code Video Model is a method rather than a tool a working creator can open and use. Running it means a Linux box, an NVIDIA GPU, a checkpoint download and about the level of setup that open model releases usually ask for.
The more interesting part is what it changes about control. Code gives a director or a technical artist levers that a prompt does not: exact camera paths, timing and physics, all editable and previewable before a paid generation runs. The edit-one-line workflow also fits how coding agents already operate, which is why the project frames the whole thing as an agent writing and revising the shot.
The evidence so far is the team's own. The demo clips were made by the people who built the system, on a benchmark they also built, so the scores show the method working under those conditions rather than a general promise. Developers who want to check the claim on their own prompts can pull the repository and the benchmark and run them locally.
Try it: clone CodeVideoModel from GitHub, download the MiniMax-H3 Ref2VA checkpoint with download_h3.py, set the OpenRouter key, and run one of the four example workspaces with inference.generate_video, or pull the CodeVideoBench cases from Hugging Face.
Sources
- code-video-model.github.io - official project page: method, early-step conditioning, benchmark scores, team
- code-video-model.github.io - tech report: abstract, Microsoft Research affiliation, judge scores against VACE
- github.com - repo: Apache-2.0 license, Ubuntu 22.04 and CUDA 12.6 install, checkpoint download, inference commands
- huggingface.co - benchmark: 22 cases, eight applications, 960x544 and 124 frames at 24 fps, CC BY 4.0 and MIT terms
- huggingface.co - MiniMax-H3 specs, reference-to-video checkpoint, community license
- x.com - co-author Gordon Guocheng Qian's October 12 announcement
- bottlerocketcontent.com - secondary coverage framing the previs analogy and the one-line edit example