Fable 5.2 is Anthropic's rescue model, and it is priced like one
Claude Fable 5.2 landed on November 9 with a 20 percent price cut, a 1M token context, a 2.5x fast mode and the best coding scores Anthropic has published. It is also slower to pay for than Opus 5.5, and the bench marks it loses matter as much as the ones it wins. A full guide, and what it changes for a video pipeline.
Key takeaways
- Fable 5.2 costs $8 per million input tokens and $40 per million output tokens, 20 percent below Fable 5.1, with a 1M token context and 128K output.
- On FrontierCode 2.0 it scores 49.1 percent against 45.5 for Opus 5.5 and 42.8 for GPT-6 Astra; on FrontierSWE v2 it scores 69.9 percent.
- Anthropic still recommends Opus 5.5 for most work. Fable is for the jobs that survive several rounds of retries, and the effort setting changes the bill more than the price cut does.
- On Claude plans, Fable draws from the same weekly limit and is capped at half of it, and the free launch resets expire between November 16, 2026 and March 8, 2027.
Anthropic shipped Claude Fable 5.2 and Claude Mythos 5.2 on November 9, 2026, and the first thing to understand is what they are not. They are not the new default. Anthropic's own guidance says to start with Opus 5.5 for most coding and knowledge work, and to move up to Fable only when your evaluations on Opus at higher effort still fall short. The second thing to understand is that Fable is the same underlying model as Mythos, with the dangerous edges sanded off: Fable carries cybersecurity and biology safeguards strong enough for general release, and Mythos is the same capability sold only to organizations verified through Anthropic's Cyber and Life Sciences programs.
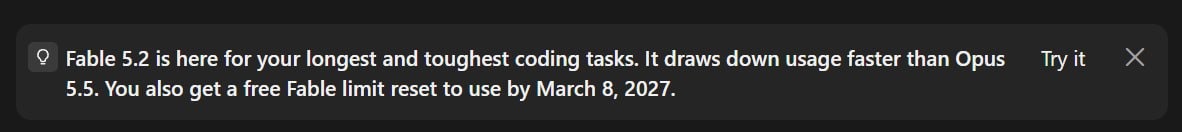
The third thing is the banner that greeted subscribers on release day: "Fable 5.2 is here for your longest and toughest coding tasks. It draws down usage faster than Opus 5.5. You also get a free Fable limit reset to use by March 8, 2027." That is the whole product in three sentences. It is better at the hardest work, it costs more of your allowance to use, and Anthropic is handing out a refund of your own limit to get you to try it.
The specification, without the marketing
- Model IDs:
claude-fable-5-2andclaude-mythos-5-2, per the model documentation. - Context: 1M tokens, default and maximum, which the docs put at roughly 555,000 words on the current tokenizer.
- Output: 128K tokens per request.
- Thinking: adaptive and always on, steered by the effort parameter. The API default effort is
high; in Claude apps and Claude Code the default ismedium. - Knowledge cutoff: June 2026.
- Standard price: $8 per million input tokens and $40 per million output, down from $10 and $50 for the 5.1 generation.
- Cache: reads at $0.20 per million, writes at $10 for five minutes and $16 for an hour.
- Batch: $4 and $20, half the standard rate.
- Fast mode: $16 and $80, double the standard rate, for up to 2.5 times the token generation speed.
- Speed: output up to 30 percent faster than Fable 5.1 even without fast mode.
- Where it runs: the Claude API, Claude apps, Claude Code, Amazon Bedrock and Claude Platform on AWS, Google Cloud, Microsoft Azure and Anthropic-hosted Foundry, and GitHub Copilot from day one.
The scores, and the scores that go the other way
Anthropic's headline numbers, as reported on release, are the best it has published:
- FrontierCode 2.0: Fable 5.2 at 49.1 percent, against 32.4 for Fable 5.1, 45.5 for Opus 5.5 and 42.8 for GPT-6 Astra.
- FrontierSWE v2: Fable 5.2 at 69.9 percent, against 65.5 for Astra, 62.3 for Opus 5.5 and 61.2 for Carbon.
Those are real gains on hard software work. But the release is not a clean sweep, and the losses are instructive. On a business-automation evaluation, Carbon beat Fable 53.9 to 51.4. On AA-Briefcase's head-to-head ranking, Opus 5.5 edged Fable 1,800 to 1,785, even though Fable more often met the written requirements. Fable is better at the work that looks like engineering and not automatically better at the work that looks like judgment.
The more important finding is about effort, and it comes from the system card, because it changes what the price cut means. Anthropic's system card reports that at Medium, Fable 5.2 beat Fable 5.1 by 5.2 percentage points at about 71 percent lower cost per task. At Xhigh it improved on its predecessor by 16.7 points but cost about 63 percent more per task, which more than eats the 20 percent list-price cut. At Max, the average cost reached $44.70 a task and the score fell below what Xhigh achieved. Cranking the dial is not a strategy. A quality target with room to dial effort down is.
What actually changed under the hood
Three things matter to anyone running it in production.
Thinking blocks are now bound to their conversation, on every account, one of four breaking changes in the release. If your code edits an earlier turn and sends the old thinking block back, you get a 400 with "The block is bound to a different conversation". On Fable 5.1 that only happened to accounts created on or after August 31, 2026; on 5.2 it applies to everyone. There is a stopgap: send the thinking-binding-controls-2026-08-01 beta header and set the prefix mismatch behavior to drop_block, which returns the dropped blocks in a top-level array. Anthropic calls it a stopgap for a reason, because dropping blocks can raise your output tokens. Also, only Fable 5.2 and Mythos 5.2 can read Fable 5.2 thinking blocks, so a mixed pipeline that hands them to an older model loses that reasoning: the API drops the unreadable block before the model sees it, and the request still succeeds.
The old computer-use tool is gone on most platforms. The computer_20251124 tool returns an error everywhere except Amazon Bedrock.
Fable can now be an advisor or an orchestrator, both documented roles in the release. As an advisor, a cheaper model does the work and consults Fable when it gets stuck. As an orchestrator, Fable plans and delegates the simpler steps to smaller models. Both are cost-control mechanisms dressed as architecture, and both are worth using, which is the subject of the second half of this piece.
The safety changes are also worth a line: Anthropic reports about 55 percent fewer blocks overall, including about 60 percent fewer in cybersecurity and 40 percent in biology, with the same underlying safeguards. When something is blocked, the fallback is Opus 4.8 for cyber and Opus 5 for biology. Outside zero-data-retention arrangements, the models carry 30-day retention for safety monitoring.
What it costs in practice
List prices are the easy part. Here is the arithmetic that matters.
The interactive session. A heavy coding run of about 50,000 input tokens and 15,000 output tokens costs roughly $1 at standard rates. Thirty of those in a day is $30. That is the shape of a working developer's Fable habit, and it is why the plan caps exist.
The invoice comparison, worked through by VentureBeat. For 10 million uncached input tokens and 1 million output tokens: $150 on Fable 5.1, $120 on Fable 5.2 standard, $240 on Fable 5.2 Fast, and $60 on Opus 5.5. The routing decision, not the price cut, is what moves the number.
The batch job. Overnight work at the Batch API rate is $4 and $20, which is the same as standard interactive Opus 5.5. If a job does not need an answer in the next minute, batching it halves the bill.
The cache. Reads at $0.20 per million mean a long system prompt, a style guide, a license list or a codebase index can sit in cache for almost nothing. For a repeated pipeline run against the same repository, this is the single biggest lever after model choice.
The plan math, and the two deadlines
On Claude plans, Fable does not come with a second allowance, as Anthropic's plan article states. It draws from the same weekly limit as every other model and is capped at half of that limit, while other models can still use the whole thing. In Settings, Usage you see two bars: your weekly limit for everything, and how much of the Fable share you have spent, each with its own reset time. Anthropic says Fable uses the limit faster than other models without publishing a multiplier.
- Free: no Fable.
- Pro at $20 and standard Team seats: normally pay-as-you-go usage credits at API rates, but through November 16, 2026 at 11:59 pm Pacific, Fable counts against the plan, up to the same 50 percent.
- Max at $100, Ultra at $200, premium Team and Enterprise seats: Fable is included, up to 50 percent of the weekly limit.
- The free reset: Pro and standard Team get one, expiring November 16. Max, Ultra and premium seats get one under six months subscribed, two from six to twelve, and three beyond that, expiring March 8, 2027 at 11:59 pm Pacific. A reset returns what you spent on Fable to your weekly limit and refills a five-hour window; it does not raise the cap, and it cannot be undone. Spend it on the week you actually need it.
Where this fits an AI video workflow
Fable 5.2 does not generate video. It will not fix a bad reference image, and it has no opinion about whether a shot is beautiful. What it does is run the engineering around the video, and that is where most of the pain in an AI video operation actually lives: the render pipeline, the sharding, the frame checks, the asset bookkeeping, the retries at two in the morning.
Here is the work, in the order it pays for itself.
1. The render orchestrator
A ten-minute 1080p piece is roughly 12,000 frames. The job is not "write a video"; it is "shard the render, run the shards in parallel, detect the failed shard, re-run only that shard, concatenate, then verify the result". That is an agentic coding task with a long horizon and a clear success test, which is exactly what Fable is for.
The loop looks like this: Fable writes the shard plan, starts the workers, watches the logs, and when a shard exits non-zero it reads the error, patches the scene, and re-runs that range only. With a 1M context it can hold the composition file, the build scripts, the timing manifest and a full stderr in one conversation without you summarizing any of it. Our own press-essay build ran 11,846 frames across two shards; the part that needed a brain was not the rendering, it was the four hours of finding out why one shard drifted.
Cost: a session like that is maybe 300,000 input tokens of code and logs and 40,000 of output, so about $4 at standard rates, or $2.00 batched if you can wait. Against a render that costs hours of GPU time, that is noise.
2. The frame QC agent
The check that catches the most embarrassing failures is also the most repetitive: pull the settled frame of every beat, look at it, and decide whether the type is legible, the contrast holds, nothing overlaps and nothing has fallen outside the frame. A model with vision and a long context can do this across a whole episode and return a list of defects with frame numbers.
The pattern that works is a hard gate, not a vibe check. Give it the composition, the timings, the frames, and the rule set, and require a pass or fail per rule per frame. Fable's vision improvements and its willingness to verify its own work are the reason this is now worth automating; the failure mode to watch is a model that reports "looks good" on a frame with 28px type, so make the rule numeric and make it cite the measurement.
3. The shot-list compiler for micro-dramas
If you are making vertical serials, the expensive step is turning a script into production-ready prompts: five to nine shots an episode, each with subject, action, camera, light and duration, each carrying the right character and location reference. That is a structured transformation over a long document, and it is the kind of thing Fable does well at high effort.
Feed it the season bible, the character sheets and the episode script, and ask for a shot table with a reference ID per shot and a prompt per shot. Then have a cheaper model do the bulk generation and keep Fable for the shots that fail twice.
4. The advisor pattern for ComfyUI and ffmpeg
The most common way to waste a frontier model is to have it write boilerplate. The most common way to waste an afternoon is a filter graph that produces a silent mix, a color space that shifts on the second pass, or a node graph that deadlocks on a queue.
This is the advisor use case, and Anthropic shipped it as a first-class role: run Opus 5.5 as the executor, and let it consult Fable 5.2 when it has failed twice. You get frontier reasoning on the hard 5 percent and Opus prices on the other 95. One caveat from the docs: with the advisor tool, a Fable 5.2 executor needs a Fable 5.2 or Mythos 5.2 advisor, so do not mix generations.
5. Localization, subtitles and rights
A season that ships in four languages has four subtitle timing sets, four dub scripts, four sets of on-screen text and a licensing trail for every asset. A 1M context is genuinely useful here: hand it the full episode manifest, the source list and the credit requirements, and have it produce per-market variants and a rights table. Then check the output, because a model that invents a license is worse than no table at all.
6. The batch farm
Everything that does not need to be interactive should go through the Batch API at half price: overnight prompt sweeps, thumbnail variants, transcript cleanups, the boring classification work that a video operation generates by the thousand. Fable is overkill for most of it, but the same pattern with Sonnet 5.5 or Haiku 5.5 is where the volume belongs.
The routing rule that keeps the bill sane
- Default to Opus 5.5. Anthropic says so, and the benchmarks agree for ordinary work.
- Escalate on evidence. Move a task to Fable when it has failed twice on Opus at high effort, not because it feels hard.
- Start at Medium effort in apps and Code, and only raise it when you can name the failure you are fixing.
- Watch the tokens, not the price. The system card's own finding is that Max effort can cost more and score worse than Xhigh. Effort is the dial that moves the bill.
- Batch anything asynchronous, cache anything repeated.
- Keep fast mode for a human waiting. Double price for 2.5x speed is worth it in a live debugging session and worth nothing in an overnight render.
The verdict
Fable 5.2 is the best model Anthropic has shipped for the work that ruins a week: the migration across an unfamiliar codebase, the render that fails only at frame 9,000, the bug that survives three rounds of diagnosis. At $8 and $40 with a 20 percent cut and a real batch discount, it is cheaper than its predecessor for exactly the jobs it is best at.
It is not a daily driver, it is not a video model, and it is not a substitute for taste. The teams that get value from it will be the ones that treat it as an escalation path with a budget, not as a personality. And the two dates matter more than any benchmark: the launch window for Pro and standard Team seats closes November 16, and the free resets expire March 8, 2027. If you are going to try it, try it on the job you have been avoiding.
Sources
- anthropic.com - the announcement: pricing, fast mode, safety, availability, the when-to-use guidance
- platform.claude.com - model ID, context, output, price, effort default, the model comparison table
- platform.claude.com - the four breaking changes, thinking blocks, the advisor requirement
- thenewstack.io - FrontierCode and FrontierSWE scores, the 20 percent cut, fast mode availability, the Medium default
- venturebeat.com - cache and batch rates, the effort cost study, the invoice comparison, where rivals win
- docs.aws.amazon.com - the model card description of long-horizon work and subagent orchestration
- github.blog - general availability in GitHub Copilot
- support.claude.com - how Fable draws from plan limits
- support.claude.com - the launch resets and their expiry dates
- fable5.app - the plan-by-plan reading of the 50 percent cap and reset allocation, checked November 10
- anthropic.com - the system card behind the effort and cost findings